RAG Systems: A Practical Guide to Architecture, Integration, and Optimization
What does it take to build a reliable, production-ready RAG system? The short answer: a clear data pipeline, a retrieval layer that finds the right information, a language model that uses that information well, and a feedback loop that improves results over time. Retrieval-augmented generation (RAG systems) combines information retrieval with large language models (LLMs), so an AI application can pull relevant knowledge from your own documents before it writes an answer. For freelancers, entrepreneurs, and digital professionals, RAG is one of the most useful AI patterns to understand, because it turns a general chatbot into a tool that knows your business. This guide walks through the architecture, the integration steps, and the optimizations that separate a demo from a system people can depend on.
What Is a RAG System?
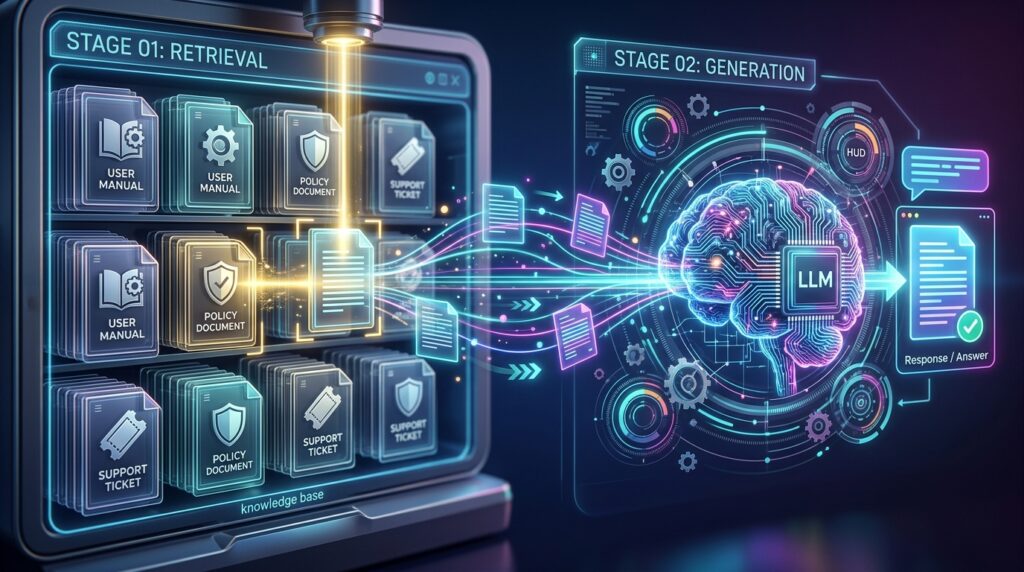
A RAG system has two main jobs. First, it retrieves the most relevant pieces of information from a knowledge base, such as product manuals, policy documents, or past support tickets. Second, it generates an answer by giving those pieces to an LLM as context.
Without retrieval, a language model answers from what it learned during training. That knowledge can be outdated, incomplete, or missing your company’s private details. With RAG systems, the model has access to your current source material at the moment it answers.
A simple way to picture it: a plain LLM is like a well-read assistant answering from memory. A RAG system is the same assistant with a filing cabinet, a librarian who finds the right folder, and the habit of checking before answering.
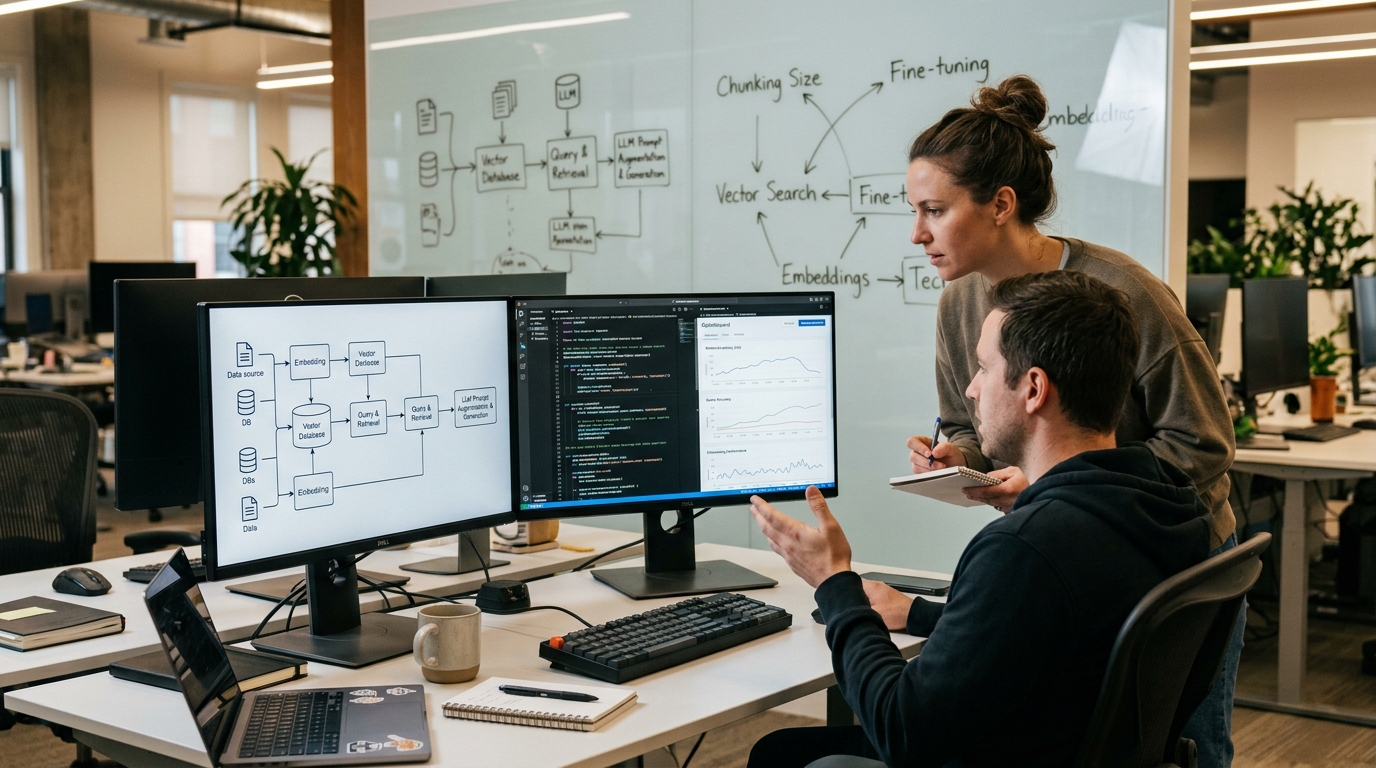
A typical RAG system includes these parts:
- Documents: The source material, such as PDFs, web pages, help-center articles, or database records.
- Chunks: Smaller pieces of those documents, usually a few paragraphs each.
- Embeddings: Numerical representations of the chunks, which allow the system to compare meaning rather than just exact words.
- Vector database: A store that finds chunks similar to a user’s question.
- LLM: The model that writes the final answer using the retrieved chunks.
- Evaluation: Tests that check whether answers are accurate and grounded in sources.
Step-by-Step Guide to Building a Production-Ready RAG System
Follow these steps in order. Each one depends on the quality of the step before it.
Step 1: Define the Problem and the Users
What to do: Decide exactly what questions the system should answer, and for whom.
How to do it: Write down five to ten real questions your users ask today. Note where the answers live now, and which answers are often wrong or slow to find. Set a clear boundary, such as “answers questions about our refund policy and product setup, and says ‘I don’t know’ for everything else.”
Why it matters: A RAG system with an unclear purpose will try to answer everything and get many things wrong. A narrow, well-defined scope is far easier to test and improve.
Example: A freelance bookkeeping consultant builds an assistant that answers questions only from her own client guides and invoicing templates. Scope is clear, so quality is easier to check.
Step 2: Collect and Clean Your Source Documents
What to do: Gather the documents the system will use and prepare them for indexing.
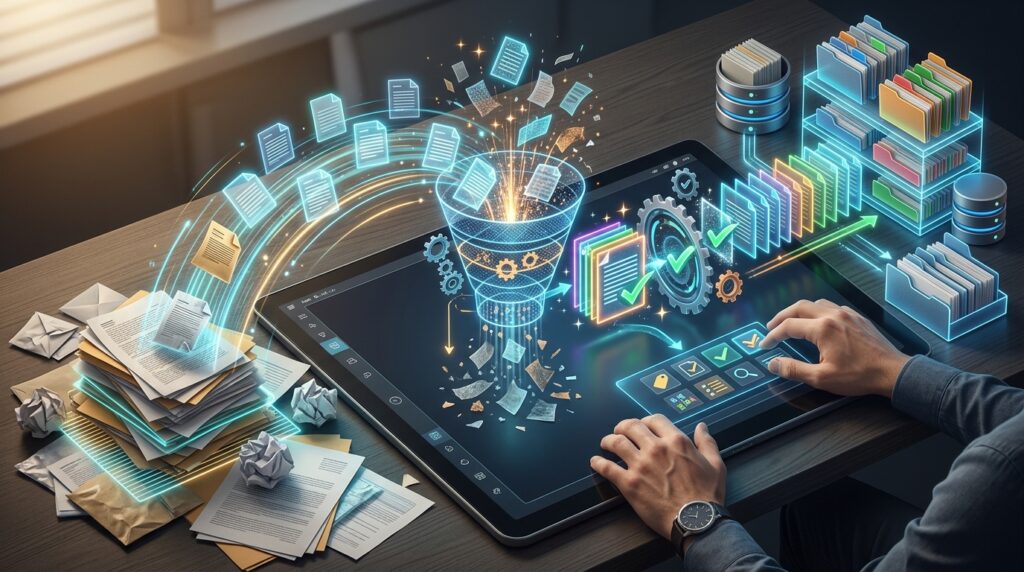
How to do it: Remove duplicates, outdated versions, and irrelevant files. Convert scanned PDFs to searchable text where possible. Record metadata for each file, such as the title, date, owner, and version. Decide who is allowed to see which documents.
Why it matters: RAG systems can only retrieve what you give them. Outdated or contradictory documents lead to confident but wrong answers, and that’s one of the most common failures in practice.
Example: An online course creator finds three versions of the same refund policy. They keep only the current one, add the effective date to its metadata, and the assistant stops quoting last year’s terms.
Step 3: Chunk Your Content Thoughtfully
What to do: Split documents into pieces the retrieval system can search.
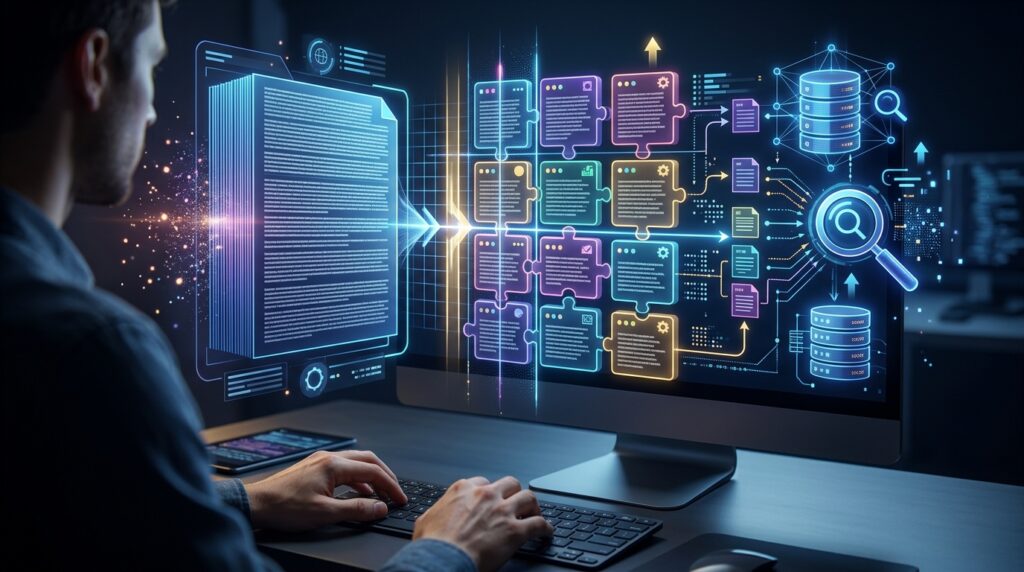
How to do it: Start with chunks of roughly 300 to 800 tokens, with a small overlap between neighbors so ideas that span a boundary aren’t lost. Split on headings and paragraphs where possible, rather than at arbitrary character counts. Keep the document title and section heading with each chunk.
Why it matters: Chunks that are too large dilute the signal, and chunks that are too small lose context. Good chunking is one of the highest-impact decisions in the whole pipeline.
Example: A section titled “Cancellation Fees” stays together, with its heading attached, rather than being split in the middle of a sentence about exceptions.
Step 4: Create Embeddings and Build the Index
What to do: Convert each chunk into an embedding and store it in a searchable index.
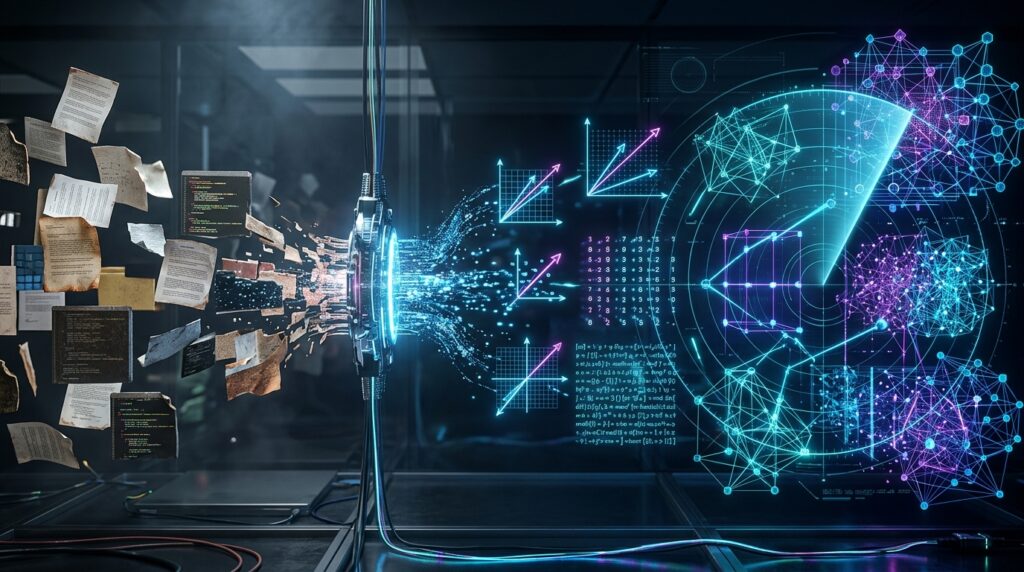
How to do it: Choose an embedding model that supports your language mix and document type. Store the vectors in a vector database or a search tool that supports vectors. Keep the original text and metadata next to each vector, so you can show sources later.
Why it matters: The index determines what the system can find. Re-indexing is costly, so it’s worth testing your embedding model on a small sample before committing.
Example: A small agency indexes its client onboarding documents and tests whether a search for “payment schedule” also finds passages that say “invoice timing.” Those results tell them whether the embedding model understands their wording.
Step 5: Build the Retrieval Layer
What to do: Design how the system searches the index and selects the chunks to send to the model.
How to do it: Start with vector search that returns the top five to ten chunks. Then add keyword search (hybrid search) for exact terms like product codes or policy numbers. Consider a reranking step that reorders the results by relevance. Limit how many chunks you pass to the model to keep answers focused.
Why it matters: Most RAG failures are retrieval failures. If the right chunk never reaches the model, even the best language model can’t give a correct answer.
Example: A user searches for “SKU-4471 return window.” Keyword search finds the exact product code, while vector search covers the general return policy. Combining both returns the right answer.
Step 6: Write the Generation Prompt and Guardrails
What to do: Tell the language model how to use the retrieved content.
How to do it: Write clear instructions: answer only from the provided context, cite the source document for each claim, and say when the context doesn’t contain the answer. Include the user’s question and the retrieved chunks in a clearly labeled format.
Why it matters: Without explicit instructions, a model may blend retrieved facts with its general knowledge and present the mix as truth. Guardrails keep answers grounded and honest.
Example: The assistant responds, “Based on the Refund Policy (updated March), refunds are available within 14 days. I couldn’t find information about refunds for bundled plans.”
Step 7: Evaluate Before You Launch
What to do: Test the system against a set of realistic questions with known good answers.
How to do it: Build an evaluation set of 50 to 100 questions, including easy, tricky, and out-of-scope examples. Score each answer for accuracy, source quality, and whether the system refuses correctly. Track retrieval results separately from generation quality, so you know where failures come from.
Why it matters: Demos look impressive but hide problems. A structured evaluation shows you what’s actually working and gives you a baseline to improve from.
Example: A consultant discovers that 20 percent of failures come from one outdated document. Fixing that single file improves the score more than any prompt change would have.
Step 8: Optimize for Speed, Cost, and Quality
What to do: Improve the system after launch, based on real usage.
How to do it: Cache answers to frequent questions. Compare smaller and larger models to find the cheapest one that meets your quality bar. Log failed or low-rated answers and review them weekly. Refresh your index when source documents change.
Why it matters: Usage costs and user expectations change over time. Regular optimization keeps the system useful and affordable.
Example: A knowledge-base tool notices that 40 percent of questions repeat. Caching those answers reduces response time and lowers model usage, while the team keeps a fresh review process for the rest.
Keep in mind that costs, performance, and timelines depend heavily on your data, tools, and traffic. Treat any figures you see in planning as estimates, and test them with your own workload.
Common Mistakes to Avoid
Most RAG problems come from a few predictable habits. Watch for these early.
- Indexing messy or outdated documents. Solution: Clean, version, and date your sources before indexing.
- Ignoring retrieval quality. Solution: Check whether the right chunks appear in the top results before you tune the language model.
- Using only vector search. Solution: Add keyword search for exact terms, codes, and names.
- Sending too much context. Solution: Pass fewer, more relevant chunks rather than flooding the model with text.
- Skipping “I don’t know” behavior. Solution: Instruct the system to admit gaps instead of guessing.
- Launching without an evaluation set. Solution: Create a test set of realistic questions and score every change against it.
- Forgetting access control. Solution: Apply the same permissions to retrieval that you use for the underlying documents, so users only see what they’re allowed to see.
Useful Tips for Beginners
- Start with a small document set. Twenty well-maintained documents teach you more than two thousand messy ones.
- Show sources in every answer. Users trust answers they can check, and you can spot errors faster.
- Log questions and answers. Real user questions are the best guide to what to improve next.
- Test with a no-code tool first. Many platforms let you prototype retrieval before writing code, which helps you learn the concepts.
- Keep chunk settings documented. When results change, you’ll know which setting caused it.
- Review failures weekly. Even ten minutes a week of reading bad answers will improve your system faster than occasional big overhauls.
- Explain the system in plain language. If a client or teammate can’t understand how answers are produced, they won’t trust them.
Frequently Asked Questions
What is the difference between RAG and fine-tuning?
RAG gives a model access to external documents at the time it answers. Fine-tuning changes the model’s behavior through additional training. RAG is often easier to update when your content changes, while fine-tuning is better suited to changing style or specialized behavior.
Do I need coding skills to build a RAG system?
Coding helps with custom systems, but many no-code and low-code platforms let you build simple RAG assistants. Basic knowledge of data formats, search, and prompts will help you get reliable results either way.
How do I know if my RAG system is working well?
Measure it with a test set of real questions. Check whether the retrieved sources are relevant, whether answers are accurate, and whether the system correctly admits when it doesn’t know. Ongoing review of user feedback matters too.
Can I use RAG to create an income opportunity?
RAG can support a freelance service, an internal business tool, or a product, but results vary widely by market, competition, and execution. Avoid promises of specific earnings. Start by solving one clear problem for one clear audience, then measure whether people value it.
Final Thoughts
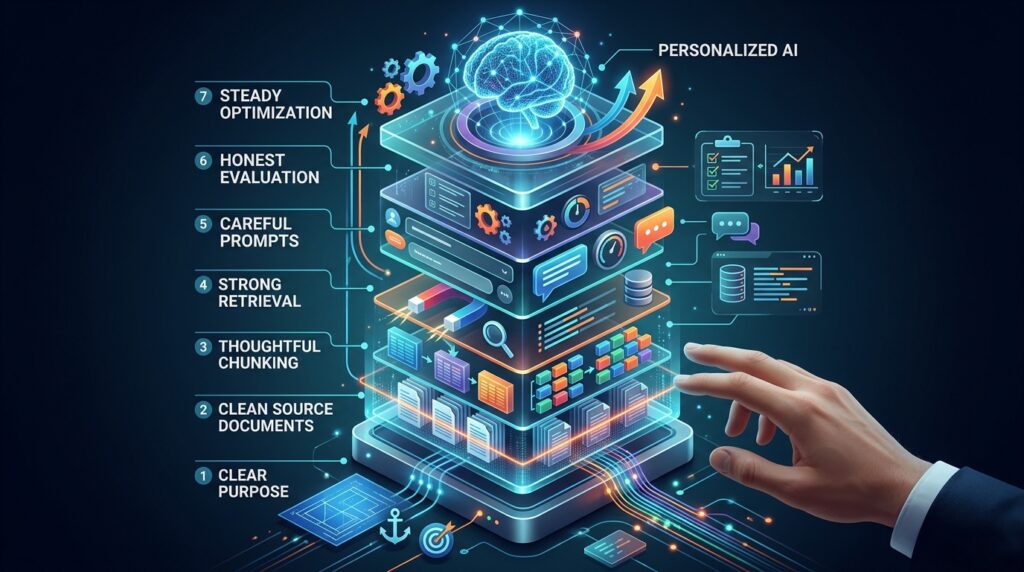
A reliable RAG system is built in layers: a clear purpose, clean source documents, thoughtful chunking, strong retrieval, careful prompts, honest evaluation, and steady optimization. Each step is manageable on its own, and together they turn a general language model into a tool that knows your material. Start small with one well-defined use case, test it honestly, and improve it based on real questions. Which step are you going to tackle first?
Click this link to read our important and interesting articles as soon as they are published!